CoreWeave2026-09-30 15:18:53CoreWeave puts NVIDIA Vera Rubin NVL72 into production, with Cognition as first live customerCoreWeave said at its Fully Connected event that its cloud platform has officially launched the NVIDIA Vera Rubin NVL72 system, paired with Spectrum-X Ethernet networking. Application AI lab Cognition is the first customer to run production workloads on the system, and CoreWeave said inference performance for Devin, Cognition’s AI software engineer, has improved on the new setup. The company also said it will offer NVIDIA Vera, which it described as the first CPU product built for AI agents. Alongside that, CoreWeave introduced CoreWeave Forge, a connected environment for training, evaluating, and improving models and agents on NVIDIA accelerated computing. According to the NVIDIA Blog, Ian Buck, vice president of hyperscale and high-performance computing at NVIDIA, said NVIDIA accelerated computing delivers value across hardware generations. He pointed to CoreWeave’s move to put Vera Rubin NVL72 into production while customer workloads are still running on V100 GPUs that were deployed years ago, calling that a sign of the platform’s strength and flexibility.70
Bitdeer2026-09-30 01:28:51Bitdeer says over 70% of capacity at Malaysia AI data center has been committedBitdeer said more than 70% of the capacity at its 21.7MW A201 AI data center in Johor, Malaysia, has already been committed. The company said the related contracts are expected to generate more than $1.7 billion in revenue over the next five years. Based on that progress, Bitdeer said signed revenue backlog for its AI Cloud business has risen to about $2.9 billion. The facility is scheduled to be energized in the first quarter of 2027. Bitdeer said the site will mainly deploy NVIDIA GB300 NVL72 liquid-cooled systems, while reserving part of the space for the next-generation Vera Rubin platform. The company also said AI projects currently under discussion exceed $10 billion in size.170
NVIDIA2026-09-11 12:06:26NVIDIA uses Palantir Foundry and cuOpt to automate global supply allocationNVIDIA is using Palantir Foundry and its open-source optimization library cuOpt to automate hardware supply-chain allocation decisions across its global manufacturing base, according to Techub News. The company has built a “digital supply chain intelligence” command center that uses mixed-integer linear programming to reduce material ownership time and manage dependencies between component supply, production constraints, and customer delivery schedules. To handle unstructured operating variables such as supplier call records, weather forecasts, and geopolitical events, NVIDIA fine-tuned its Nemotron 3.5 Lightning model for the domain. On historical allocation records, the tuned model reached 86.7% decision accuracy, outperforming both the untuned base model and the larger Nemotron 3 Ultra model. The fine-tuning process took only minutes on two B200 GPUs. NVIDIA said the supply-chain network it is preparing for the Vera Rubin architecture will be twice the size of the network supporting Grace Blackwell. Operational choices, planning revisions, and actual factory output data will continue to be written back into Palantir’s ontology model.300
Pequity Resea2026-09-09 00:48:11FundaAI says GPT-6 training compute is about 10x GPT-5Pequity Research, citing FundaAI, said GPT-6 used roughly 10 times the training compute of the GPT-5 generation. FundaAI also said that, based on industry discussions, the compute consumed by experiments, reinforcement learning, synthetic data generation and supporting infrastructure could amount to several times the main pre-training run, with the upper end reaching 10 times. It added that once TPU 8t and Vera Rubin ship at scale, the next round of pre-training acceleration could begin, with large-scale interconnect and optics set to benefit the most in that cycle. The note focuses on how total compute demand may extend well beyond the headline pre-training run and points to hardware delivery as a key condition for the next step in model training acceleration.890
Nvidia2026-09-07 12:46:09Nvidia said to weigh nearly $3 billion into Mira Murati’s Thinking Machines Lab at a $40 billion valuationNvidia is reportedly in talks to put nearly $3 billion into Thinking Machines Lab, the AI startup founded by former OpenAI CTO Mira Murati, according to the input material. The company is seeking $5 billion to $6 billion at a pre-money valuation of at least $40 billion, with Nvidia potentially covering about half of the round. The report says this would extend an existing relationship rather than start a new one. In March 2026, Nvidia and Thinking Machines Lab announced a multi-year strategic partnership to deploy at least 1GW of Vera Rubin systems, alongside a separate undisclosed investment by Nvidia. The startup had previously raised a $2 billion seed round in July 2025 at a $12 billion post-money valuation, backed by Andreessen Horowitz, Accel, Nvidia, AMD and Jane Street. The input also outlines the company’s product rollout: the Tinker fine-tuning platform launched in October 2025 and fully opened in December, followed by the July 15, 2026 debut of Inkling, a model with 975 billion total parameters, 41 billion active parameters, a 1 million-token context window, multimodal input support and open weights. The same source notes that Nvidia separately signed a deal on Sept. 3 to acquire Hugging Face for $12.9303 billion, putting model distribution, fine-tuning infrastructure and chips on the same strategic map.1700
South Korea2026-09-07 05:58:10South Korea’s Vera Rubin NVL72 budget sets implied price at $20.7 million per rackSouth Korea’s next AI compute procurement plan has drawn attention after the Ministry of Science and ICT confirmed a 3.85 trillion won budget for next year’s GPU server expansion. The entire amount is earmarked for 140 NVIDIA Vera Rubin NVL72 server racks, implying 27.5 billion won, or about $20.7 million, per rack. That figure is far above estimates previously published by Bernstein and Morgan Stanley. According to Money Today, citing a project document obtained by the office of Democratic Party lawmaker Lee Jeong-heon, each rack includes 72 Rubin GPUs and 36 Vera CPUs, bringing the planned total to 10,080 Rubin GPUs. The ministry said the budget also reflects possible price increases tied to tight GPU supply, along with installation and infrastructure costs. The procurement has also been linked to South Korea’s AI policy ambitions. Deputy Prime Minister and Science Minister Bae Kyung-hoon said in June that developing a model at the level of Anthropic Mythos would require about 10,000 Vera Rubin units. The report also noted that actual NVL72 transaction prices remain unknown, as current figures from Wall Street firms are analyst estimates rather than official NVIDIA pricing.1060
South Korea2026-09-07 00:32:31South Korea Budgets 27.5 Billion Won Per Rack for Nvidia Vera Rubin AI ChipsSouth Korea's Ministry of Science and ICT has unveiled its budget for Nvidia's next-generation Vera Rubin AI chips, planning to allocate 27.5 billion won per rack in 2027—far exceeding earlier estimates. The total budget of 3.85 trillion won will fund 140 NVL72 racks, each equipped with 72 Rubin GPUs and 36 Vera CPUs, delivering a total of 10,080 Rubin GPUs. This procurement is separate from the ministry's previously announced plan to acquire 52,000 advanced GPUs by 2028. The chips are intended for developing AGI and other frontier AI models. Bernstein had estimated the rack cost at $9.1 million, and Morgan Stanley at $7.8 million, both below the government's figure. Deputy Prime Minister and Minister of Science and ICT Lee Jong-ho said in June that training a model comparable to Anthropic's Mythos would require about 10,000 Vera Rubin GPUs, making this batch roughly equivalent.950
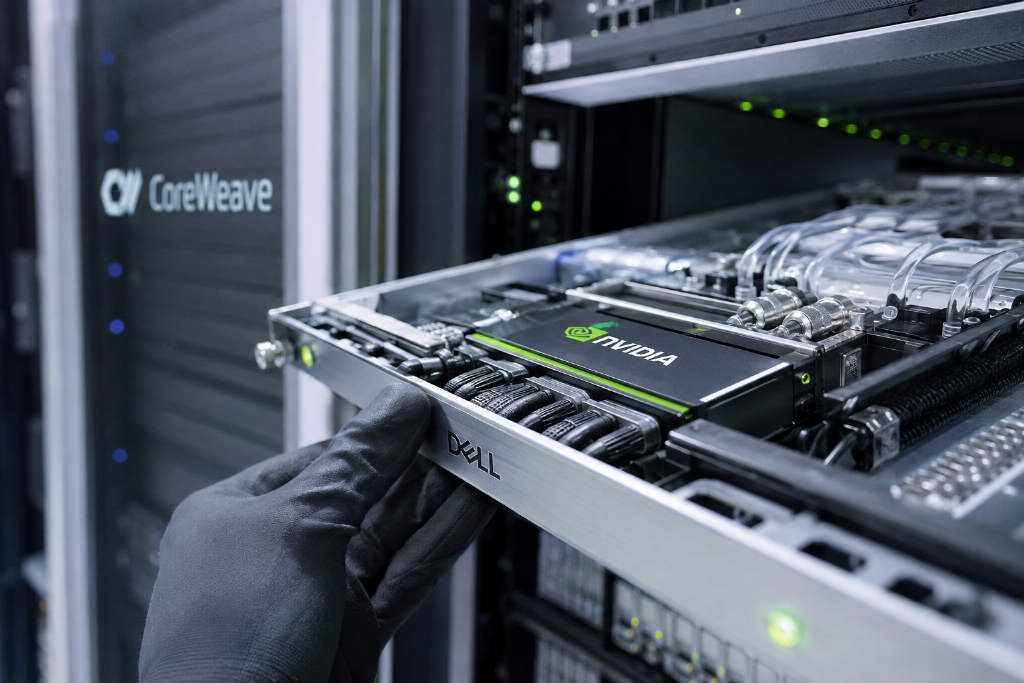
Dell2026-09-04 22:44:51Dell Ships First Nvidia Vera Rubin NVL72 AI Server Racks to CoreWeaveDell Technologies has delivered the inaugural Nvidia Vera Rubin NVL72 AI server racks to CoreWeave, marking a milestone in AI efficiency and potential cost-energy reduction.840